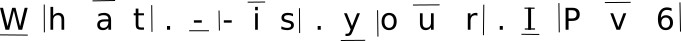Wednesday, January 22, 2025

A leg workout machine for homes.


I call it KneeCruncher.


Sunday, December 1, 2024

SQL injection flaw and how to fix it at DB itself


One simple example is 

Select * from Users where email = '$email' ;

Here $email could be substituted with an "OR" getting a positive result for the condition check.

$email could be ' OR '1'='1 (including the single quotes), making this a valid SQL Statement. 

However, In DB we could add a SQL Command template for the SQL statement, and if the template doesn't match then the SQL statement doesn't get executed. 


email_value = web_input;

db->connection(""" , '"", 5000);

db->set_statement (" Select * from Users where email = '"+ email_value +" ';");

db->set_valid_template( " select * from Users where email = '%'; "); 

// where % represents a value that is added dynamically. 

if( db->is_injected() ){

    //SQL injection detected

    //return error.

} else {

    //SQL injection not detected

    // continue on here ...

}

Instead of fixing this in a website (backend pages) this could be fixed in the DB parser level itself, making one of the security vulnerabilities fixed.

Or, something like this can be done.

db->check_sql( email_value ) 

//0 - not sql

//1 - partial sql statement

//2 - full sql statement


Both of these methods wouldn't require a db query to be done.


Monday, July 26, 2021

Power of 2 : Updated

 Here is the correct algorithm, basically it wasn't taking 1 as input properly.


#include <iostream>

#include <thread>

#include <chrono>

using namespace std;


uint64_t powerxxx(int x, int n) {

if (n <= 0) {

if (n == 0)

return 1;

else

    return 0;

}


int modval = n & 0x01;

if (modval == 1)

n--;

int count = (n >> 1);

int powertwo = x*x;

uint64_t power = 1;


while (count > 0)

{

power *= powertwo;

count--;

}


if (modval == 1)

power *= x;


return power;

}


int main()

{

auto start = std::chrono::system_clock::now();

uint64_t p = pow(3, 33);

auto end = std::chrono::system_clock::now();

std::chrono::duration<long double> diff = end - start;

std::cout << "power = " << p << ": " << diff.count() << " s\n";


start = std::chrono::system_clock::now();

p = powerxxx(3, 33);

end = std::chrono::system_clock::now();

diff = end - start;

std::cout <<"power = "<<p <<": " << diff.count() << " s\n";

return 0;

}

Power of 2 : :)

This is a new algorithm to calculate pow(x, n), where it calculates nth power of x. According to Chrono it is faster than the system pow(x,n).


#include <iostream>

#include <chrono>

using namespace std;


uint64_t powerxxx(int x, int n) {

int count  = 0;

int modval = n & 0x01;

if (modval == 1)

n = n - 1;


if (n == 0)

return 1;

else if (n < 0)

return 0;

count = (n >> 1);

int powertwo = x*x;

uint64_t power = 1;


while (count > 0)

{

power *= powertwo;

count--;

}


if (modval == 1)

power *= x;

return power;

}


int main()

{

auto start = std::chrono::system_clock::now();

uint64_t p = pow(3, 33);

auto end = std::chrono::system_clock::now();

std::chrono::duration<double> diff = end - start;

std::cout << "power = " << p << ": " << diff.count() << " s\n";


start = std::chrono::system_clock::now();

p = powerxxx(3, 33);

end = std::chrono::system_clock::now();

diff = end - start;

std::cout <<"power = "<<p <<": " << diff.count() << " s\n";


    return 0;

}

Sunday, January 29, 2017

CodeDetective : A source code studying tool

Finally the alpha release of my source code studying tool is ready. Its called CodeDetective. This version is a pre-release so it could be buggy, as long as it doesn't crash i would say its good, also, its missing a lot of things at this time.  

Features:
  1. It supports ctags, It also comes with ctags binary taken from the ctags website. In order to search tags, run "ctags -Rn" in the project folder and it should be able to read the ctags tags file to perform regexp search over tags.
  2. It comes with find and grep functionality.
  3. The default page is called study, where in if you open files and close them it records this information , also it records your bookmarks, find (also uses regexp) files searchs, findgrep searches and tag searches.
  4. You can record Todo, Note and some small pieces of code for later references.
  5. Its not an IDE, its a source code studying tool. Wouldn't recommend saving files using this.
  6. It comes with fakevim editor that has been integrated with it. So, you can use vim commands(basic) after clicking on the editor itself.
Here is the url: https://github.com/r9al/CodeDetective/releases How to use:
  1. Use the explorer tree to select the appropriate folder.
  2. Click on "Set as Project Folder" in "Project" menu. (Open project is no longer relevant so no need to even click them)
  3. Search away.
  4. Once done save study and close project.

Wednesday, May 11, 2016

#unicodeipv6: The converter program

The url for the source code (#unicodeipv6) is :

https://github.com/r9al/ipv6unicode/


Tuesday, May 10, 2016

#unicodeipv6: Represent an IPv6 address in a 4X4 Matrix

Represent an IPv6 address in a 4X4 Matrix

Here are some of the valid ipv6 addresses written in 4X4 Matrix.


#unicodeipv6 : The Summary

#ipv6 #unicodeipv6

( Base64 Characters * 4 combinations ) = 256 Characters ;
16 Characters * 8 Bits = 128 Bits (IPv6 Address)


Monday, May 9, 2016

Facebook Page created

Characters in #unicodeipv6


The above image show characters with values from 0-63.


The above image show characters with values from 64-127.


The above image show characters with values from 128-191.


The above image show characters with values from 192-255.

2 new slogans for #unicodeipv6


Support #unicodeipv6


Use the hashtag #unicodeipv6

If you like the idea then use the hashtag #unicodeipv6 on twitter or facebook.

The Idea

Saturday, May 7, 2016

Anoop's Method : Representing IPv6 addresses in a new way

The Problem:

The biggest problem that is with the IPv6 representation is that 128bits requires a lot of characters representing it. A problem I thought of and came up with a unique solution, may not be a perfect solution but it a lot easier than the current one (Wikipedia Explanation) which only network admins can understand. This I feel is one of main reason why its adoption has been less.

With 128 bits for address you will need 32 characters to represent a single IPv6 address (each character representing 4 bits) if the current Base16 is Used. However you look at it, its going to consume that many characters. If the vast majority of the characters are going to be zeros then omitting them is a nice idea which is the current solution that IPv6 uses. What does that mean to the layman ? How does he configure the ip address of his machine ? The IPv4 itself is confusing for a simpleton but with IPv6 it changes the whole approach of thinking. Although it may appear as self-explanatory the simplcity of typing 192.168.0.1 or something similar is totally disregarded in the IPv6 representation. This doesn't mean that I am IPv4 fanboy or anything. I just love the idea of simplicity. In stark contrast I actually feel IPv6 should be adopted and soon. It will drastically change the world. The problem remains with the representation.


My Solution:
Base256 (or Anoop's Method)

The obvious question will be : it will require 256 different characters to represent each of the 256 values. Not to mention people have to remember them, and how is this supposed to help the anyone?

And that is where I would say "I beg to differ".

I said 256 different characters not 256 different characters to remember.

So let me explain, does anyone know base64 encoding ? it uses 64 characters to represent 64 values, I am just borrowing that idea.

The 64 Characters are ofcourse :
ABCDEFGHIJKLMNOPQRSTUVWXYZabcdefghijklmnopqrstuvwxyz0123456789+/
10 - numbers
26 - Small letters of english
26 - Capital letters of english
plus and slash (Atleast I think its + and /) - that makes it a total of 64 characters.

Personally I prefer having the following character set in this order:
0123456789ABCDEFGHIJKLMNOPQRSTUVWXYZabcdefghijklmnopqrstuvwxyz-+

So how does 64 characters = 256 values. This is where you got to love the idea of simplicity.

Now how do I convert 64 values to 256 values ?
Rotate it Clockwise or Anticlockwise with marker indicating direction of the character (this is Method 2) or better yet put a line marker in the direction of North, East, South, West (Or Top, Right, Bottom, Left), making every single character have 4 possible combinations. That means 64X4 = 256 characters.


The picture above represents two ways of having 256 Values from 64 Characters. 

So an ip address would like this:
OR (Second Method, is to use the line marker with character rotation )
NOTE: These new 256 characters (first method) should be made available in Unicode characters list specifically for IPv6 Representation or 4 new Modifier characters have to be included in the Unicode characters list. The second method is a little more complex to read and has slight flaws depending on the font that is being used.

That would make it 8Bits * 16 = 128Bits
Representing IPv6 or IPv4 address would be a lot simpler using the this method.

Console Environment: (ASCII representation)
Since these alphabets with markers donot exist as of today, there has to be an ascii representation for console only machines. In that case we would require 32 characters as before. As we need a prefix for each character to identify whether it is South Marker Capital Letter 'A' ,  West Marker Capital Letter 'A', North Marker Capital Letter 'A'  or East Marker Capital Letter 'A' .

The same address would look something like this:
SAWBNCED.WENFEGSH.NIEJSKWL.EMSNWONP

Example:
S1S2S3S4.W1W2W3W4.N1N2N3N4.E1E2E3E4
NaNbNcNd.EeEfEgEh.SiSjSkSl.WmWnWoWp

Subnet Mask Example:
E+E+E+E+.E+E+E+E+.E+E+E+E+.E+E+E+S0

The prefix being S-SOUTH, W-WEST, N-NORTH, E-EAST . The prefix should always be capital letter and every letter has a prefix if you are using ASCII representation. The spaces are present to improve readability.

GUI Environment:
And for the GUI environment a Popup window that lists the primary base256 characters along with the marker type(NORTH, EAST, SOUTH, WEST) can be provided to configure an ipaddress/subnet... etc.


IPv4 Representation :
IPv4 also can be represented using this method, which requires only 4 characters.


Character Representation and its values:
Should the characters values be uncollated or collated as in do we assign values like this:

Method 1: (SWNE Method, SOUTH-WEST-NORTH-EAST)
S0 = 0, W0 = 1, N0 = 2,  E0 = 3, S1 = 4, W1 = 5,  N1 = 6,  E1 = 7

or

Method2:  (4S Method or SSSS Method, SOUTH SOUTH SOUTH SOUTH Method)
S0 = 0, S1 = 1, S2 = 2,  S3 = 3, S4 = 4, S5 = 5,  S6 = 6,  S7 = 7, ... , S- = 62, S+ = 63 , W0 = 64, ... so on and so forth.

Personally I think method 2 for value association is better and more readable.

Some common values:
0 = S0
1 = S1
255 = E+

Short Cut to Fast Typing of IPv6 Characters

A + CTRL + Arrow UP = NA
a  + CTRL + Arrow UP = Na
1  + CTRL + Arrow RIGHT = E1
... Etc